A product startup that also builds for you
IREVEX builds its own AI products, starting with Beyond Queries, and takes on a small number of engineering projects for other teams. It is small on purpose: no account managers, no discovery deck, and the first conversation is with the engineer who would do the work.
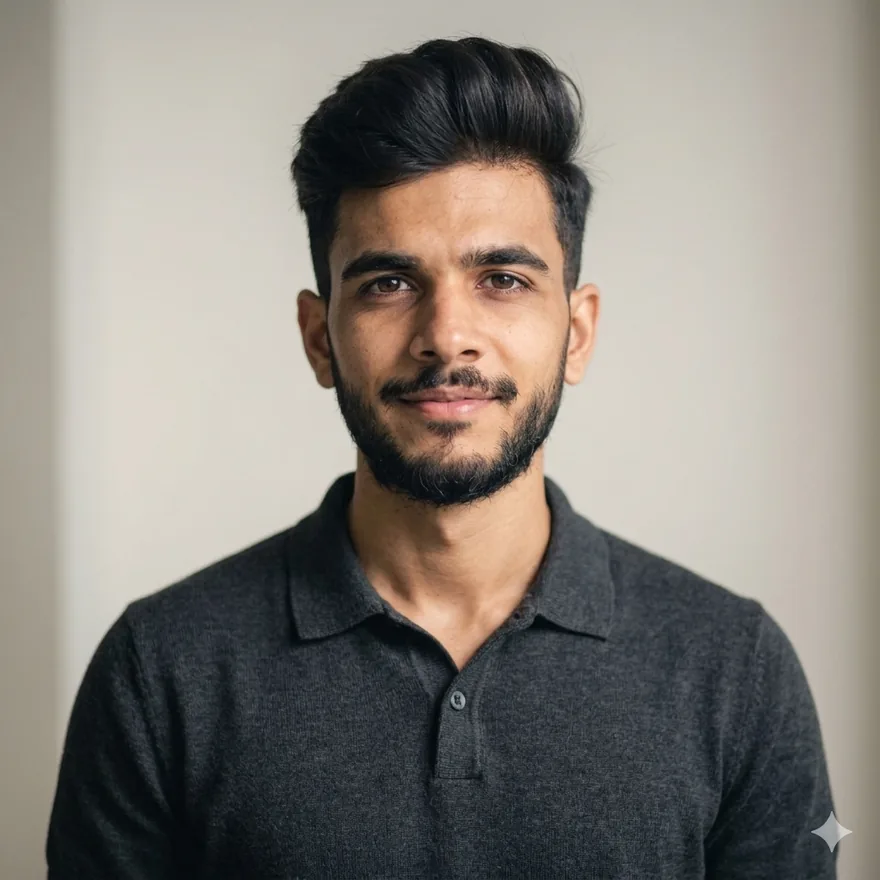
Ibad ur Rehman
AI Engineer · Karachi, Pakistan
I started IREVEX because the interesting problem in this field is not getting a model to answer. It is knowing whether the answer is right. Beyond Queries is that idea built as a product. The services work is the same idea applied to someone else’s system.
Three years of that has been agents, retrieval and voice pipelines in production, which mostly means three years of finding out how they break.
- Focus
- Agents · Retrieval · Voice
- Backend
- Python · FastAPI · Celery · Redis
- Data
- PostgreSQL · Qdrant · Milvus · pgvector
- Cloud
- AWS · Azure AI · Runpod
- Education
- BS Software Engineering, UIT
- Since
- 2023
Where the experience comes from
Dec 2024 —
AI Software Engineer
Kodexo Labs
AI architecture and backend for client systems in logistics, fleet diagnostics, customer support and healthcare.
- Warehouse text-to-SQL
- Designed and built the AI layer for a plain-English interface over 207 tables across four databases. A LangGraph router reads each question and decides whether it needs the database or the documentation; the SQL path then plans the query, prunes the schema down to the relevant columns, generates, and validates before anything executes. The model never sees the whole schema. Query accuracy moved from roughly 75% to above 90%.
- Repair-procedure retrieval
- Re-architected a 160,000-row repair lookup away from semantic similarity and onto text-to-SQL, then rebuilt how nested procedures are walked. References go on a stack and the agent is shown only the next five steps. Some faults run ten references deep with ten or more steps each, which no single-pass agent handled reliably. The rewrite made the traversal deterministic and cut the cost of resolving one fault.
- Multi-tenant agent builder
- A drag-and-drop workflow builder with retrieval, code execution, API and Zendesk tools, drafting ticket replies from each tenant's own documentation for a human agent to approve. The retrieval tool runs plain RAG, query transformation or CRAG depending on the flow, over a ten-million-vector Milvus store with per-tenant isolation.
- Voice cost reduction
- Moved a medical intake product off a hosted voice API onto self-hosted LiveKit with a cheaper model, holding response quality, and added call teardown when an examinee stops responding rather than leaving the line open.
- Coaching agent determinism
- Rebuilt an open-ended agent loop as an explicit state machine with controlled transitions. Accuracy went from 60% to 95%, and the hallucinated guidance in user-facing reports stopped.
- Call analytics backend
- FastAPI services behind an SQS queue, so scoring a backlog of sales-call recordings runs in the background instead of blocking request throughput.
2023 – 24
Machine Learning Engineer
Bleed AI (remote, US)
Retrieval systems, agent harnesses and voice pipelines across more than ten client projects, delivered fully remote for a US company.
- Creator persona platform
- Per-persona prompt templates so each bot held a distinct voice rather than one house style, with Instagram and X posts ingested as live context so a bot knew what had just happened in that creator's week. Open models served on vLLM and RunPod to keep per-conversation cost viable at consumer pricing.
- Retrieval accuracy
- Reranking, hybrid search and dynamic chunking on a production RAG system, worth about twenty percent on retrieval accuracy.
- Client delivery
- IVR and Twilio call assistants, tool-use agents and speech pipelines, deploying GPT-4, Claude, LLaMA 2 and 3 and Mistral across SageMaker, Fargate, EC2 and RunPod.
2023
AI R&D Intern
Appedology
Insurance document extraction, built before retrieval tooling existed to build it with.
- Extraction from papers
- No LangChain, no vector database worth the name. The system was assembled from research papers, benchmarking Orca, Vicuna and Falcon, with DocQuery answering directly off scanned images.
- OCR and ingestion
- Ensemble OCR lifted extraction accuracy seventy percent on irregular scans, and the chatbot ingestion pipeline went from thirty-five minutes to ten.
Four numbers that are real
75 → 90%
Query accuracy on a plain-English interface over 207 tables, after the planning and schema-pruning stages went in.
60 → 95%
Coaching agent accuracy, after an open-ended loop was rebuilt as an explicit state machine.
50%
Inference cost removed by self-hosting open models on vLLM instead of a cloud API.
35 → 10
Minutes, for a chatbot ingestion pipeline on one dataset.
Figures are from work delivered at Kodexo Labs, Bleed AI and Appedology, and describe those systems rather than IREVEX’s.